Benchmark • AI models • confidence & cost
JEV Sat
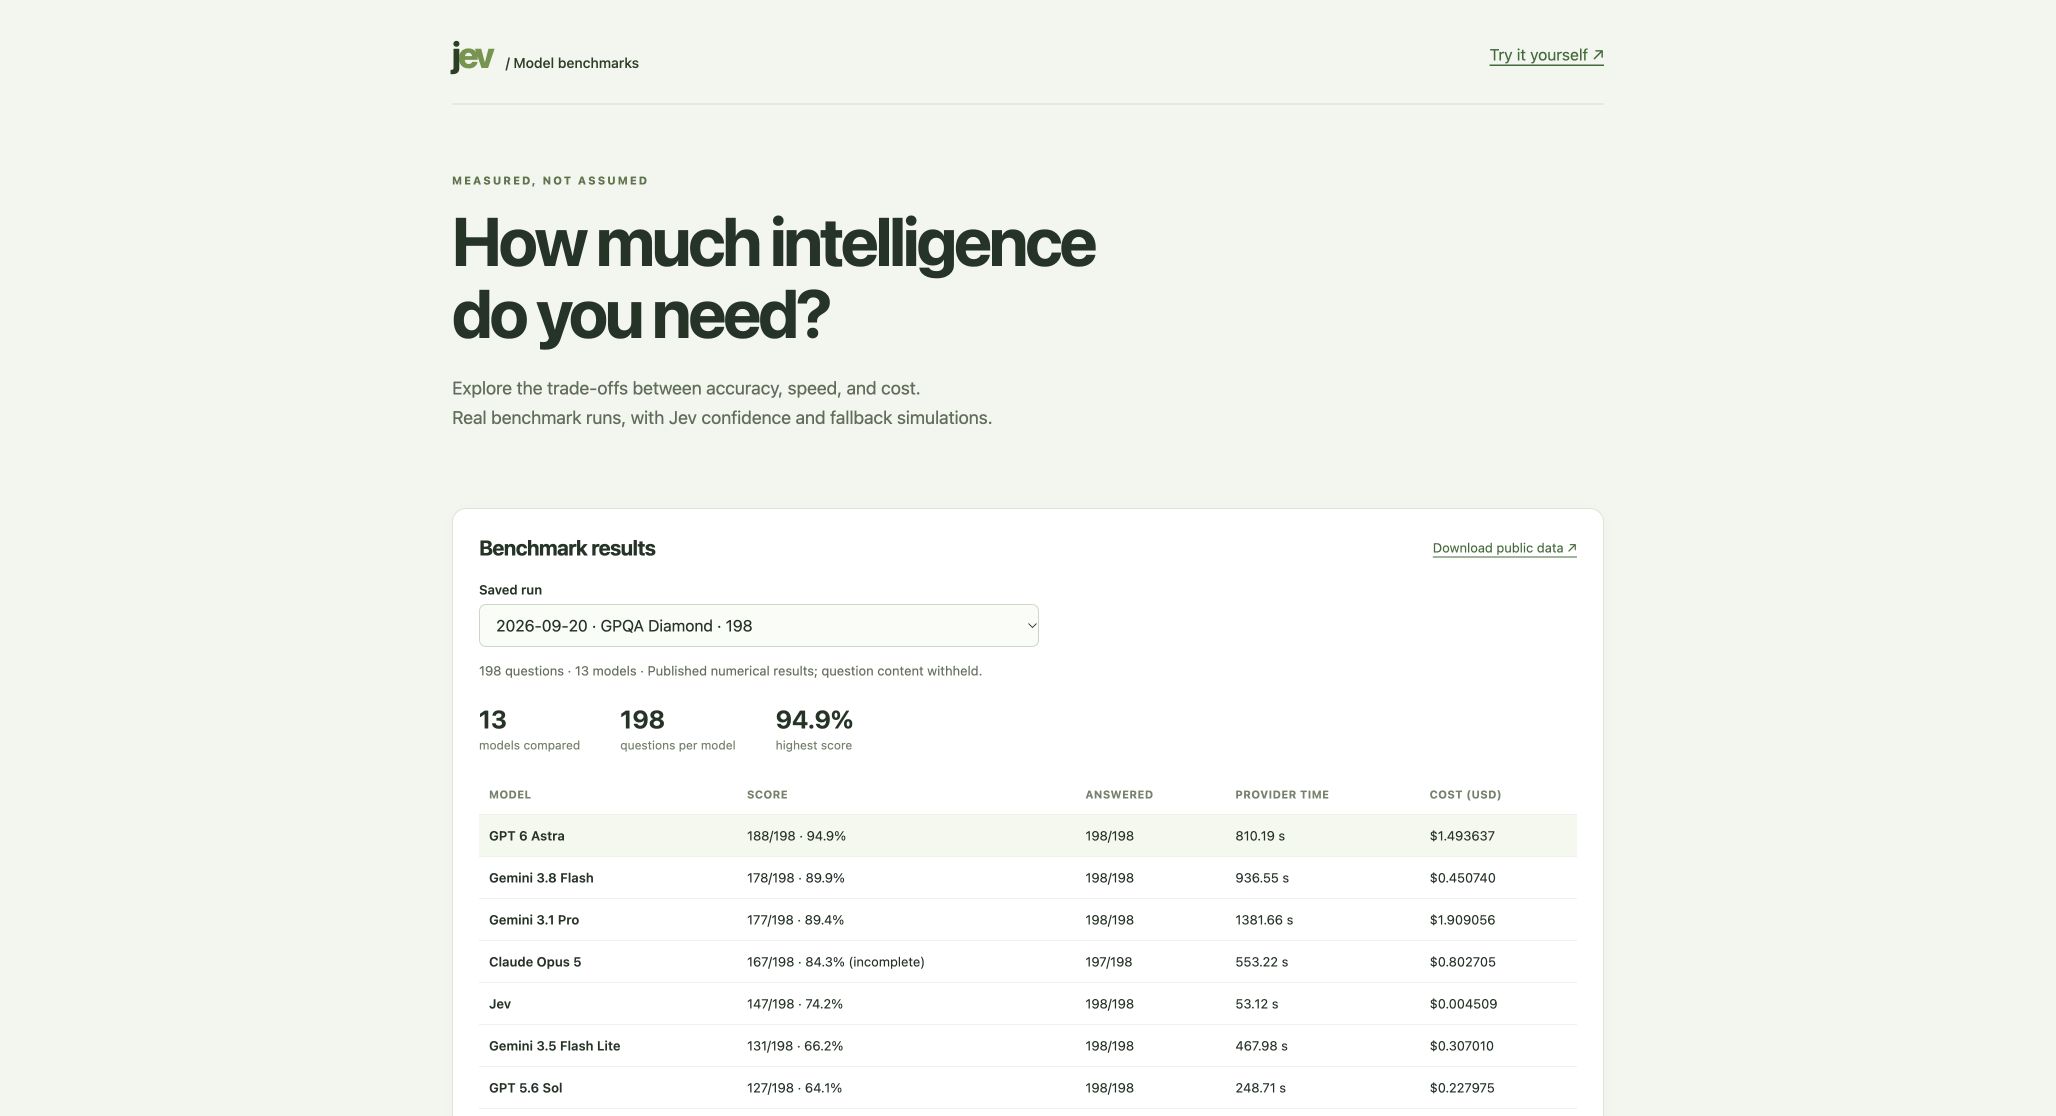
Explore AI benchmark results across accuracy, speed, cost, and confidence, simulate model fallbacks, or run original questions with your own API key. JEV Sat brings published numerical results into an interactive comparison of model performance and resource use. Confidence thresholds show how routing answers to a fallback model changes the simulated outcome. A separate playground offers ten original SAT-style questions using your own Vercel AI Gateway key. The historical comparisons are exploratory, with provider time, cost and incomplete results shown alongside scores.